A 145-billion-parameter model running on a laptop sounds like a typo. Edge0 says it is not. Its newly open-sourced Edge0-145B can run locally on a compatible MacBook Pro-class machine, with 29GB peak memory and more than 80 output tokens per second in the company’s tests.
Treat those figures as vendor claims until independent reviewers reproduce them. Still, even a cautious reading makes this release worth paying attention to. Local AI has mostly meant accepting a smaller, slower model in exchange for privacy and no per-token bill. Edge0 is trying to make that trade less painful for coding agents and long document tasks.
Ask whether enough of a team’s repetitive AI work now fits on a machine it already owns. That is a more useful test than chasing a universal cloud-model ranking.
Why 145B fits in 29GB
A dense 145B model would not fit into laptop memory. Edge0-145B is a sparse mixture-of-experts model: it contains many parameter groups, but activates roughly 10B parameters for each token. That distinction matters. Total parameter count describes what is available; active parameters describe how much computation happens on each step.
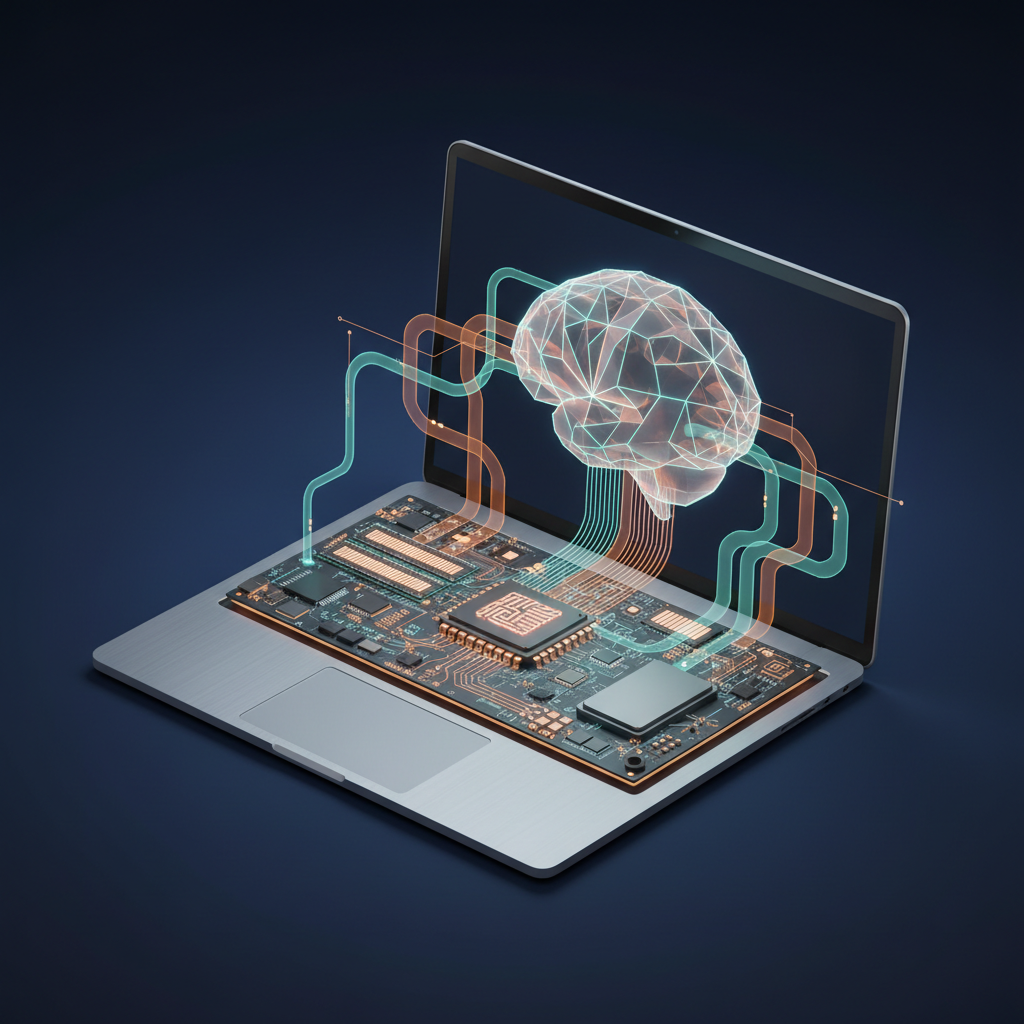
Edge0 also changes where model data lives. Its inference runtime splits work across three tiers:
- GPU memory handles immediate computation.
- System RAM holds an expert library of roughly 40GB.
- SSD storage supplies about 48GB of vocabulary data when needed.
The runtime pipelines reads across those tiers, schedules CPU and GPU work together, and uses speculative decoding to reduce waiting for weights. That is a lot of engineering aimed at one constraint: consumer devices have fast chips, but not unlimited unified memory.
This is more interesting than a benchmark screenshot. If the approach works outside a controlled demo, it gives local-model developers another path besides buying an expensive workstation or renting GPUs.
Read the benchmarks with eyes open
Edge0 reports a 72.8 mean score across six benchmarks at 29GB measured memory. It also reports 64.6 on DeepSWE 1.1, 90.4 on GPQA-Diamond, and 86.52 on Terminal-Bench 2.1. The company compares its DeepSWE result favorably with Qwen3.8-Flash-Next and says its model reaches more than 80 tokens per second while decoding.
Those numbers are promising, but they are Edge0’s own measurements. Benchmarks depend on prompts, harness settings, tool permissions, quantization, and the exact laptop used. A coding-agent score also says less about your repository than vendors would like. Your codebase has its own dependencies, conventions, test failures, and messy tickets.
So do not replace a production API because a launch post says you can. Run a contained evaluation first. Use the same task set across models, preserve logs, and compare completed tests instead of judging polished-looking answers.
Where local inference wins already
Local models earn their keep on work where data control, repeat volume, or unreliable connectivity matters more than squeezing out every last capability. Dramatic autonomous-agent demos can wait.
Sensitive internal material
Customer contracts, incident reports, source code, HR documents, and financial planning files all become harder to govern once they leave your environment. An offline app does not remove every security concern, but it removes an external API call from the workflow. Edge0 says its desktop app runs without an account, and it has released the weights and inference framework publicly.
“Local” still needs disk encryption, access control, secure model downloads, and rules about what tools an agent may invoke. Keeping inference on-device gives security teams a smaller data path to inspect.
High-volume routine work
Token pricing is easy to ignore on one-off chats. It becomes visible when an agent repeatedly reads repositories, drafts tests, summarizes support tickets, or processes a large document set. A local model trades usage fees for hardware, electricity, setup time, and someone who can keep it running.
That trade often favors APIs for bursty or demanding work. For steady internal workloads, local inference can become cheaper because the marginal cost of another task is small once the machine is in place. Measure this with your own task volume, not a generic cost calculator.
Work that cannot wait for network access
A local model can help during travel, in restricted environments, or when a vendor outage blocks an otherwise ordinary task. It also makes a useful fallback: route routine drafting and code navigation locally, then reserve cloud calls for tasks where a stronger model materially improves the result.
A practical test plan for Edge0-145B
Start small. One developer and a non-critical repository are enough to learn whether this belongs in your stack.
1. Check hardware before downloading
Edge0’s reported setup relies on substantial memory and fast local storage. Confirm your machine matches the supported configuration and reserve disk space for model assets. The launch material cites about 29GB peak memory, roughly 40GB for its expert library, and about 48GB of vocabulary data. Do not assume a laptop with the same RAM number will behave the same way.
2. Build a 10-task evaluation set
Pick tasks your team can score without taste-based arguments: fix a failing unit test, explain an unfamiliar module, write a migration plan, locate a regression, or prepare a pull-request summary. Include a task that should fail safely, such as a request that needs missing credentials. Keep inputs scrubbed of secrets.
Record pass rate, time to a reviewed answer, token speed, memory pressure, battery or power draw, and how often a human had to repair the output. A model that is fast but creates subtle defects costs more than it saves.
3. Run it beside your current API workflow
Use the exact same tasks with your existing cloud model. Give both systems the same repository state and tool permissions. Then compare completed test suites alongside benchmark-like scores. If the local model handles navigation, boilerplate, and test drafting well, route those tasks to it. Keep cloud models for difficult debugging, broad research, or work requiring the best available reasoning.
4. Set hard boundaries for agent access
Local inference does not justify unrestricted shell access. Require confirmation for destructive commands, use a disposable branch or container, block production credentials, and keep command logs. These controls are boring. They are also the difference between a useful assistant and an unattended process with too much permission.
The part Edge0 still has to prove
Edge0 has released weights in NVFP4 format, an inference framework on GitHub, and an offline desktop app. That makes it testable, which is better than another closed demo. It also released Edge0-120B and previously announced a 35B phone model.
But launch-day claims are not operating data. Independent tests need to establish which laptop configurations work, whether the 80-plus token rate survives real agent loops, how often SSD traffic becomes a bottleneck, and how model quality holds up on ordinary repositories. The company should also publish reproducible benchmark instructions and raw task traces.
For now, Edge0-145B is a serious claim with open materials behind it. Cloud APIs still win when you need top-tier capability immediately, elastic capacity, or vendor-managed infrastructure.
What changed is the starting assumption. A local model no longer has to be a tiny emergency option. For a growing set of private, repetitive tasks, it may be the default lane. Test it on real work before you believe the headline. If the results hold, your next AI budget discussion gets much more interesting.
Source: Edge0, “Introducing Edge0-145B: Frontier AI Capabilities on Your Own Computer”, published November 12, 2026. Performance figures in this post are vendor-reported unless otherwise noted.