When the benchmark failed the model
GPT-5.6 Sol scored 7.8% on ARC-AGI-3, a benchmark that tests how well AI agents reason through unfamiliar 2D puzzle games. That number is bad. Embarrassing, even. The previous GPT-5.5 model scored 0.4% on the same test.
The OpenAI team assumed they had a capability problem. They were wrong.
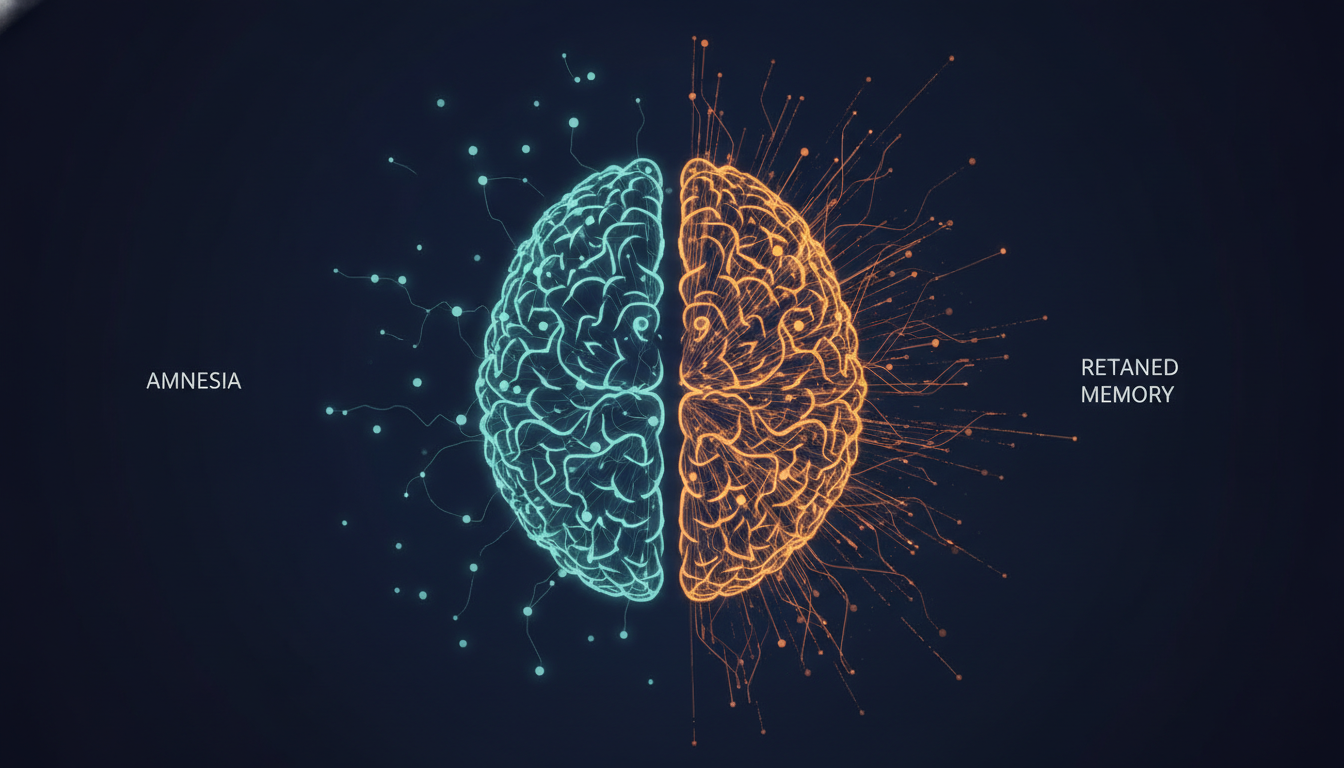
The problem was memory. Specifically, the benchmark’s default harness was throwing away the model’s reasoning after every single action. Imagine playing chess where, after each move, someone wipes your understanding of the board. You’d make bad moves too.
When OpenAI turned on two settings they already use in production — retained reasoning and compaction — the score jumped from 13.3% to 38.3% on the public task set. The model cut its token usage by 6x in the process. Same model. Same benchmark. Different configuration.
The average human scores about 48% on this test.
What actually happened
ARC-AGI-3 runs on a deliberately generic harness. No special features, no optimizations. That design choice, meant to keep comparisons fair, created two problems:
-
Private reasoning was discarded after each action. When GPT-5.6 Sol thought through a move using chain-of-thought reasoning, that thinking vanished the moment it acted. Next turn, it started from scratch.
-
Older actions got truncated. As the game progressed and context grew, the harness used rolling truncation — cutting off the oldest context to make room for new. The model literally forgot what it had already done.
Combine amnesia of the present with erasure of the past, and you get a model that has to re-derive the game rules on every single turn. It never gets to build on what it learned.
The fix came down to two API settings:
- Retained reasoning keeps the model’s chain-of-thought between turns. The model remembers what it figured out last turn.
- Compaction summarizes older context instead of deleting it. The model keeps a compressed but complete picture of game history.
Turn both on and the model starts behaving like a player who can remember the board, recall its strategy, and adapt. The score tripled. Token output dropped by a factor of six because the model stopped re-deriving everything from scratch.
Why this matters beyond benchmarks
Here’s the part that should matter to anyone building with AI right now: this is not a benchmark curiosity. This is a production problem hiding in plain sight.
If you’re running an AI agent that handles multi-step workflows — customer support tickets, code refactoring, research synthesis, document processing — and that agent seems to go in circles or repeat mistakes, the model probably isn’t the bottleneck. Your harness is.
Most production agent setups make one or both of these mistakes. They either discard the model’s reasoning between steps (treating chain-of-thought as disposable output rather than state), or they truncate context aggressively to manage token costs (losing important history in the process). The result looks like a dumb model. The cause is configuration.
The cost implications are direct. OpenAI’s data shows that the compaction approach didn’t just improve scores — it cut token usage by 6x. Agents that remember what they’re doing don’t waste tokens re-explaining the task to themselves. Better results, lower cost.
How to check your own setup
Three questions to ask of any agent pipeline you’re running:
Does your agent retain its reasoning between steps? If you’re using a standard chat completion loop, the model’s chain-of-thought is likely discarded after each turn. Check whether your framework supports reasoning retention or persistent memory layers. OpenAI’s Responses API, Anthropic’s extended thinking, and several agent frameworks now offer this.
How does your context window get managed? Rolling truncation is the default in most setups, and it’s the most destructive. The oldest context gets cut, which is often the most important — the original task, early decisions, constraints established at the start. Compaction (summarizing old context rather than deleting it) is the better approach, and it’s increasingly available as a built-in feature.
Are you measuring agent quality at the step level or the outcome level? If you only look at whether the final output is correct, you’ll miss agents that stumble repeatedly but eventually arrive at the answer. Step-level evaluation catches the amnesia pattern — you’ll see the model re-asking questions it already answered, or re-deriving facts it already established.
The broader shift
The ARC-AGI-3 result points to something bigger than one benchmark score. We’re moving past the era where “which model is best?” was the only question that mattered. The model is increasingly a commodity. The harness — how you feed it context, how you manage its memory, how you structure its workflow — is where the real performance differences live now.
OpenAI made this explicit in their post. They recommend always using the Responses API with retained reasoning and compaction for long-running agent tasks. Not sometimes. Always. Because the alternative is paying for a frontier model and then crippling it with a harness that gives it amnesia.
The teams that figure out harness design will pull ahead of the teams that don’t, even if everyone is using the same underlying models. The model is the engine. The harness is the transmission. You can have a Ferrari engine, but if the gearbox strips out after every shift, you’re not going anywhere fast.
What to do now
-
Audit your current agent setup. Check whether reasoning is retained between steps and how context is managed. If either is broken, you’re likely losing performance you’ve already paid for.
-
Test with compaction enabled. If your provider supports context compaction, enable it and measure the difference in both quality and cost. The ARC-AGI-3 data suggests the improvement is large and the token savings are real.
-
Evaluate at the step level, not just outcomes. Build instrumentation that tracks what your agent does at each step, not just whether the final result was correct. You’ll catch memory failures that outcome-only metrics hide.
-
Read the original post from OpenAI. It’s short, specific, and the data tables are clear. The link is in the attribution below.
The headline “two settings tripled the score” is accurate but undersells it. The real lesson is that agent intelligence is partly the model and partly the infrastructure around it. Right now, a lot of teams are paying for the model and ignoring the infrastructure. That’s the expensive mistake.
Based on reporting from OpenAI’s ARC-AGI-3 post-mortem, published July 31, 2026. The original analysis is available at openai.com.